
Lower your AI bill and protect your margin, without losing quality.
See what every fix is worth in one week. Then ship the ones that pay.
For Seed to Series B SaaS teams with LLM features in production. In one week, the audit shows what each successful answer really costs you, where quality is slipping, and which fixes save the most per month, each checked so quality holds. Hands-on implementation, quoted separately, then ships those fixes with your team, so the savings show up on your bill.
Free · 30 minutes · no prep. You leave with your 3 likeliest cost leaks and roughly what each costs you per month.
- 10+ years building SaaS and AI systems
- FinOps Certified Practitioner
- Model tokens
- Retrieval / context
- Infra around the call
- Eval runs
- Human review & retries
The gap between the two bars is what failed requests cost: retries and the people who check them. Per-request dashboards never show it.
show --numbers
| layer | per_request | per_outcome |
|---|---|---|
| model_tokens | 0.0062 | 0.0086 |
| retrieval_context | 0.0021 | 0.0029 |
| infra_around_call | 0.0011 | 0.0015 |
| eval_runs | 0.0006 | 0.0008 |
| review_and_retries | 0.0004 | 0.0072 |
What it's worth to your business
Every finding comes with a dollar figure, so the decision is a business one: which fixes pay back, how fast, and what happens to your margin as usage grows.
Lower AI spend
Fixes ranked by estimated monthly saving, so you start with the ones that pay most.
Healthier gross margin
A cost model that shows what AI costs per customer as usage grows, so pricing and plans keep their margin.
Fewer failures customers see
Where answers fail and what that costs in retries and support time. No saving is recommended if quality drops.
The payback math
The audit is a fixed $5,000; implementing the fixes is quoted separately. If the fixes it finds are worth about $420 a month, it pays for itself within a year, and you see each fix's dollar value before committing to anything else.
- Audit price
- $5,000
- fixed · pilot free
- Pays back at
- ~$420/mo
- in savings, within a year
- Time to the numbers
- 1 week
- Commitment after
- None
- implementation is optional, quoted separately
Why LLM features quietly eat into margin
List prices are rarely the problem. Spend and failures grow together: context that's larger than it needs to be, retries nobody tracks, regressions nobody catches before users do, and the largest model doing jobs a smaller one would pass. Each one shows up as spend, support load or churn.
Context size
Every extra RAG chunk is paid for on every call.
Retries
A failed answer is paid for twice, sometimes more.
Eval runs
Needed, but they grow quietly with every regression suite.
One model for every task
The largest model handles jobs a smaller one would pass.
Everything around the call
Logging, vector stores and data transfer sit outside the model invoice.
Sound familiar?
“Our Bedrock bill doubled, and usage didn't.”
“Our AI usage is growing, and our gross margin is shrinking.”
“Every time we try a cheaper model, someone complains about quality.”
“We find out about regressions when customers report them.”
- Model tokens
- Input and output tokens per call, by model. Usually the largest line, and the one most changed by model choice and prompt size.
- Retrieval / context
- Embeddings, vector store and RAG chunks. More context makes every call cost more, often with no gain in quality.
- Infra around the call
- Compute, logging, data transfer and queues. Easy to miss because it isn't on the model invoice.
- Eval runs
- Every eval and regression run costs tokens. Needed, but it should be sized, not left unbounded.
- Human review & retries
- Failed outputs that get retried or checked by a person. This is where cost per request and cost per successful outcome drift apart.
Who it's for
A fast, one-week audit is built for a specific kind of team. If yours isn't a fit, I'll tell you directly on the call.
Good fit
- Seed to Series B SaaS teams based in the US, EU, UAE, Singapore, Australia, or New Zealand.
- LLM features already live in production
- On AWS (Bedrock) or direct API providers such as OpenAI and Anthropic
Not a fit
- Teams that need a month-long vendor onboarding. The audit runs in one week, so procurement has to clear first.
- Teams where read-only access takes weeks of approvals. The audit needs access on day 1.
- Teams without an LLM feature in production yet. The audit measures live traffic, not plans.
How the audit works
One LLM feature, one week, read-only. A fixed, published price, and every finding priced in dollars per month.
- What you get
- The dollar value of every fix, ranked
- Timeline
- 1 week
- Access
- Read-only, under NDA
- Price
- $5,000
- fixed · pilot free (3 places)
Who it's for: seed–Series B SaaS with LLM features in production.
# day 1
Measure
Read-only access set up; pull billing exports, provider usage and traces, including failure, retry, latency and fallback rates.
→ deliverable
Baseline cost per successful outcome and per request, plus failure, retry, latency and fallback rates
# day 2
Attribute
Map the feature's spend to the 5 cost layers.
→ deliverable
The feature's spend split by the 5 cost layers
# day 3
Find
Identify fixes: context trimming, routing, caching, retries.
→ deliverable
Candidate fixes, each with an estimated $/month
# day 4
Verify with evals
Build the golden eval set from production traces; run each fix against it and check its latency and fallback rates.
→ deliverable
Golden eval set + pass rate, latency and fallback rate before and after each fix
# day 5
Rank by $
Rank fixes, build the cost model, write the report; readout call.
→ deliverable
Fix list ranked by $/month, cost model and report
What you leave with
Where the money goes, what each fix saves, and the tools to keep it that way. Everything stays with your team. Formats shown with synthetic numbers.
Audit report
Where the feature's AI spend goes today, by cost layer.
Fix list ranked by $/month
Each fix with its saving, effort and the eval result.
Golden eval set, yours to keep
Ready to gate model and prompt changes in CI.
Cost model
Projects spend as usage grows, before the bill arrives.
Price every fix first. Then ship the ones that pay.
A one-week, read-only audit puts a dollar value on every fix. Hands-on implementation ships them in your repo, highest saving first, so the savings reach your bill. Each step is quoted separately at a fixed price, and none is required.
- 01Booking now
AI Cost & Reliability Audit
In one week: what one LLM feature really costs, where it fails, and which fixes save the most per month, with quality checked. $5,000 fixed, pilot free.
- 02Follows the audit
Hands-on Implementation
The audit's highest-saving fixes, shipped in your repo with your team and measured in dollars against the baseline. 4–8 weeks.
Also available: Cloud Cost Audit · SaaS Unit Economics & Margin Audit
Building in public
There are no client case studies here yet. This is where the proof stands, and what comes next.
- Now
Pilot program open
2 of 3 placesFree audits for 3 teams, in exchange for an anonymized case study, a short testimonial and a 30-minute feedback call.
- Next
LLM Bill Teardown #1
PlannedWhere a SaaS team's model spend actually went, and which fixes held quality.
- Next
Open-source eval gate
PlannedA small GitHub Action that runs a golden eval set on every pull request and blocks changes that drop the pass rate.
How I think
Measure cost per successful outcome, not cost per request.
A cheap request that fails costs more than an expensive one that works, in retries, support time and churn. Divide spend by the outcomes users actually got.
No eval, no cost cut.
A cost cut that quietly lowers quality isn't a saving. Every change is checked against an eval before it's recommended.
Architecture before pricing.
Most spend is set by how the system is built (context size, retries, model routing), not by the price per token.
Fixes ship in your codebase, not in a slide deck.
A finding only counts once it's merged, gated by evals and measured against the baseline. The report says what to change; the implementation changes it.
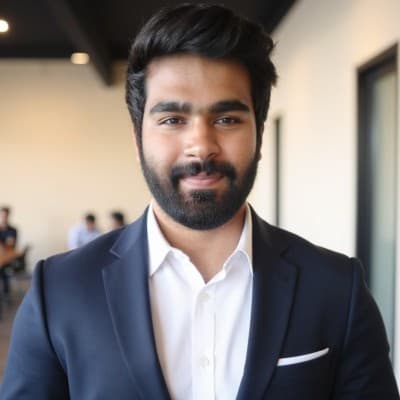
10+ years building SaaS and AI systems.
AI engineer working on production LLM systems: evals, RAG, agents and the infrastructure around them on AWS. FinOps Certified Practitioner, so cost is measured alongside quality from day one.
- Based in India (IST)
- Calls Mon–Fri, 9 AM–7 PM IST: early morning US East, working hours EU, UAE and Singapore, afternoon ANZ. Everything else is driven by written async updates in between.
Get a free 30-minute cost check
Free, 30 minutes, no prep needed. You leave with the 3 most likely cost or reliability leaks in your LLM feature, a rough idea of what they cost you each month, and a clear answer on which engagement, if any, is worth it.
No pitch if it's not a fit.
Before the call, the booking form asks:
- 1What is this call about?
- 2What stage is your company at, and roughly how large is the team?
- 3What's the main problem right now, and roughly what does it cost you per month?
- 4What would make this call valuable for you?
Prefer email? [email protected]
Free cost check
30-min video call
Weekly availability
Mon–Fri · 9 AM–7 PM IST
No prep. You leave with your 3 likeliest cost or reliability leaks.
Choose a timeOpens right here. No sign-up needed.